A 9B Agent Model from Xiaomi — Code, Tool Use and Software Screenshots
MiMo-V2.6-Distill-Qwen-9B is Xiaomi's 9-billion-parameter agentic model, fine-tuned from Qwen3.5-9B on data generated by Xiaomi's larger MiMo models. Give it a text prompt and up to two images and it answers in text. It is strongest on coding, tool use and reading screenshots of software. MIT license.
📸 See it in action
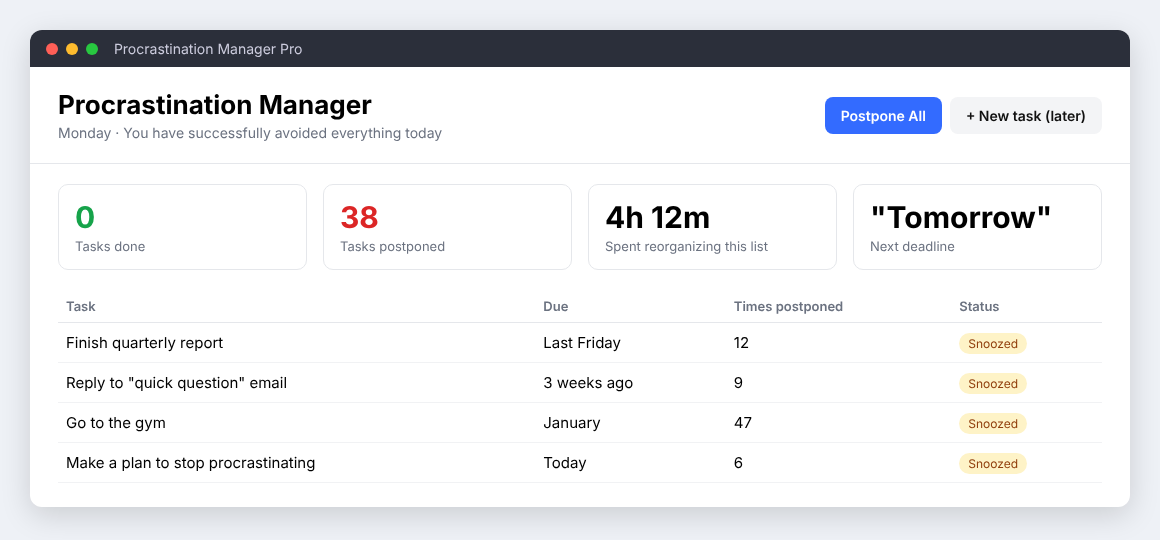
Screenshot to code. A screenshot of a (made-up) productivity app and one request: explain it, then write the button's code. Default settings, thinking off.
Prompt
Here is a screenshot of an app. In one sentence, say what the app does and how its user is doing. Then write the JavaScript for the "Postpone All" button: it should move every task's due date to tomorrow and add 1 to its "Times postponed" count. Keep the code short.
MiMo-V2.6-Distill-Qwen-9B's answer (unedited)
This procrastination tracker shows a user who has done nothing yet (0 tasks done, 38 postponed) and is spending their day reorganizing the list; the "Postpone All" button pushes every task's due date to tomorrow and bumps its "Times postponed" count by one.
The screenshot is a mock-up we built for this example. The class names (.task, .due, .times) are the model's guess — a screenshot doesn't show the real HTML, so adapt them to your markup.
What it does
MiMo-V2.6-Distill-Qwen-9B takes a text prompt and, optionally, one or two images, and returns a text answer. It was trained on 77.4B tokens split across code (29.9%), general agent tasks (28.5%), visual tasks (27.4%) and cybersecurity (14.2%), so it is at its best when the job looks like an agent's job: read a UI screenshot, write or fix code, plan steps, or produce structured output for the next node.
It is built to reason before it answers. In CNAPS Studio, thinking is off by default so ordinary prompts return quickly; switch it on for multi-step tasks.
Xiaomi released this checkpoint as a starting point for open research in agentic reinforcement learning — it is a supervised fine-tune, not a finished chat product.
Problem it solves
Use case | How it helps |
Read software screenshots | Describe a UI, find a button, read an error dialog, list form fields |
Screenshot to code | Turn a screenshot of a page or component into HTML/CSS or a short script |
Code help in a flow | Write, fix or explain code passed in from an earlier node |
Plan agent steps | Break a task into ordered steps or tool calls |
Compare two images | Feed both image ports and ask what changed between two screens |
Input/Output
Input
- Text (required) — the prompt or question
- Image 1 (optional) — a reference image or screenshot
- Image 2 (optional) — a second image. With both connected, the model can compare the two together with the prompt
Parameters
Parameter | Details |
max_new_tokens | 1–8192, default 2048 (advanced). Cap on response length. Raise it when thinking is on — the reasoning block spends tokens before the answer. An answer that stops mid-sentence usually means this cap |
temperature | 0–2, default 0.0 (advanced). 0 is greedy and deterministic. Any value above 0 turns on sampling and makes top_p and top_k take effect |
top_p | 0–1, default 0.95 (advanced). Nucleus sampling; ignored at temperature 0 |
top_k | 1–100, default 20 (advanced). Limits candidates to the k most likely tokens; ignored at temperature 0 |
enable_thinking | On / Off (default, advanced). Off answers directly. On lets the model reason first — how the checkpoint was trained, and better on agentic and multi-step tasks — but it can use the whole token budget reasoning, so raise max_new_tokens with it |
Output
- Text — the generated response
Benchmarks
From Xiaomi's model card, comparing this SFT checkpoint with its base, Qwen3.5-9B:
Benchmark | Qwen3.5-9B | MiMo-V2.6-Distill-Qwen-9B |
SWE-bench Verified (avg@3) | 60.0 | 61.1 |
SWE-bench Pro (avg@3) | 32.0 | 44.6 |
Terminal Bench 2.1 | 27.0 | 37.1 |
Toolathlon-Verified | 25.9 | 35.2 |
AutomationBench v1.0.6 | 5.0 | 30.3 |
OfficeQA | 9.0 | 19.5 |
These are the provider's own results, not measured in CNAPS Studio.
Technical Details
Base model | Qwen3.5-9B |
Training | Supervised fine-tune on MiMo-generated data — 77.4B total tokens (27.2B loss-bearing) |
Parameters | 9B |
Precision | bf16 |
Thinking | Part of the chat template; this node defaults it off |
Runtime | GPU, cloud — no local setup |
Compliance & Provenance
Provider | Xiaomi (MiMo) |
Provider type | Open-source |
License | MIT |
EU AI Act risk class | Limited Risk |
Art. 50 transparency | Applicable — multimodal LLM output carries the AI-generated label |
Region availability | Available globally |
Training data summary | Pending — provider has not yet published per Art. 53(d) |
Xiaomi's model card also lists use restrictions, including no malicious cyber activity, no military use and no unauthorized processing of personal data. For more on how we classify models and mark outputs, see our AI Policy.
Model Source
- Model card
- License: MIT
How MiMo-V2.6-Distill-Qwen-9B compares
Model | Best for | Notes |
MiMo-V2.6-Distill-Qwen-9B | Code, tool use, software screenshots | 9B; MIT |
Qwen3.6-35B-MoE | Coding, agentic tasks, step-by-step reasoning | SWE-bench Verified 73.4% |
Qwen3.8-27B | Very long inputs with images | 262K-token context |
Gemma 4 31B | General reasoning over text and images | MMLU Pro 85.2% |
SenseNova-Loop-9B-Preview | Agent and office tasks at 9B with extra depth | Looped transformer; preview |
MiniCPM-V 4.7 35B A3B | Images, several at once, efficient MoE | ~3B active |
MiniCPM-V 4.7 1B / Gemma 4 E2B | Light, high-volume tasks | Smallest options |
Mage-VL | Documents and charts | 4B |
Rough guidance: Qwen3.6 if you want the strongest coding model, MiMo-V2.6 when a smaller 9B agent model is enough, Gemma 4 31B as the general default. Scope notes come from each node's own documentation; the models have not been benchmarked against each other inside CNAPS Studio.
All of these run inside CNAPS Studio — compare them side-by-side.