Japanese Document OCR — Vertical Text, Tables and Formulas
Reads Japanese and English documents and returns markdown, with tables as HTML and formulas as LaTeX. Handles vertical Japanese text, which the other OCR models in the catalog do not. 4B VLM from SB Intuitions, MIT licensed. Japanese and English only.
What it does
Sarashina2.2-OCR is a 4-billion-parameter vision-language model built for Japanese document reading. Give it a page image and it returns two things: the extracted text as markdown, and an image with the detected figures and charts marked.
It is the only model here that reads vertical Japanese text (縦書き), and the structure it recovers goes beyond plain text — tables come back as HTML, formulas as LaTeX. That makes it the right pick for Japanese contracts, technical papers, textbooks, and financial statements, where the layout carries meaning.
Japanese and English only. It will not read Korean, Chinese, or anything else.
About the image output: it marks figures and charts only, not every text block. Visual components are located with bounding boxes on a normalized 0–1000 coordinate range. If you want the full page layout boxed, use GLM-OCR instead.
Problem it solves
Japanese documents | Contracts, filings, manuals, textbooks — including vertical text |
Tables | Returned as HTML, ready to parse downstream instead of retyping |
Formulas | Returned as LaTeX from technical papers and textbooks |
Figure & chart detection | Marked on the output image so you can crop or count them |
Markdown output | Headings and structure preserved, not a flat text dump |
Input/Output
- Input: A document page image
- Format: JPG, PNG, WEBP, AVIF
- Content: Any document page — contracts, papers, forms, textbook pages, statements
- Language: Japanese or English only
- Output: Two ports
- Image — the page with detected figures and charts marked, using normalized 0–1000 bounding boxes. Not a full layout box map; GLM-OCR does that
- Text — extracted text as markdown, with tables as HTML and formulas as LaTeX
Example: handwritten Japanese memo
We ran Sarashina2.2-OCR on a neat handwritten-style memo: a meeting note on lined paper, slightly tilted, with a title, a bullet list, times and a closing line. One node, default settings, no prompt.
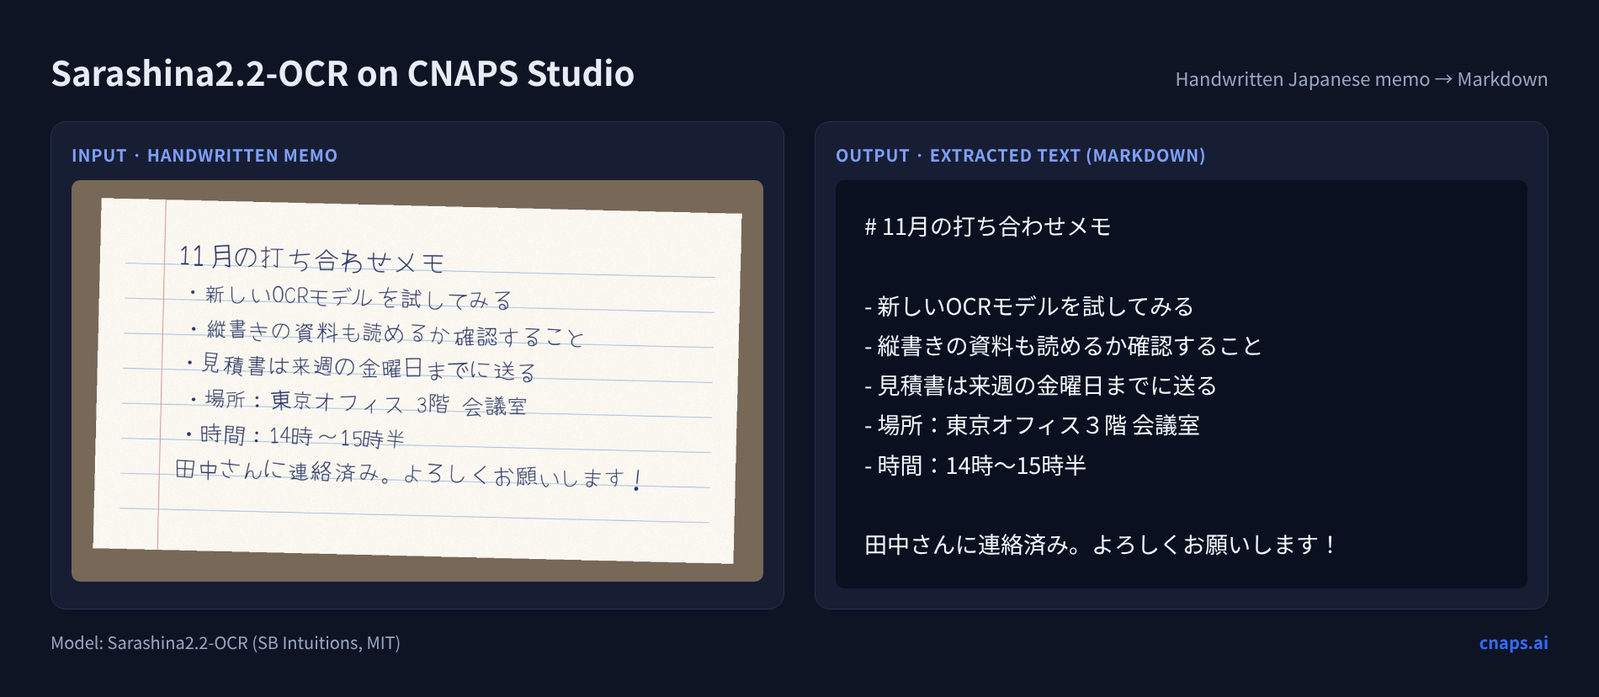
Every line came back correct. The model also turned the note into proper markdown on its own: the title became a heading and the bullets became a list. The only difference was the "3" in 3階, which came back as a full-width "3". The run took about 30 seconds, including model loading.
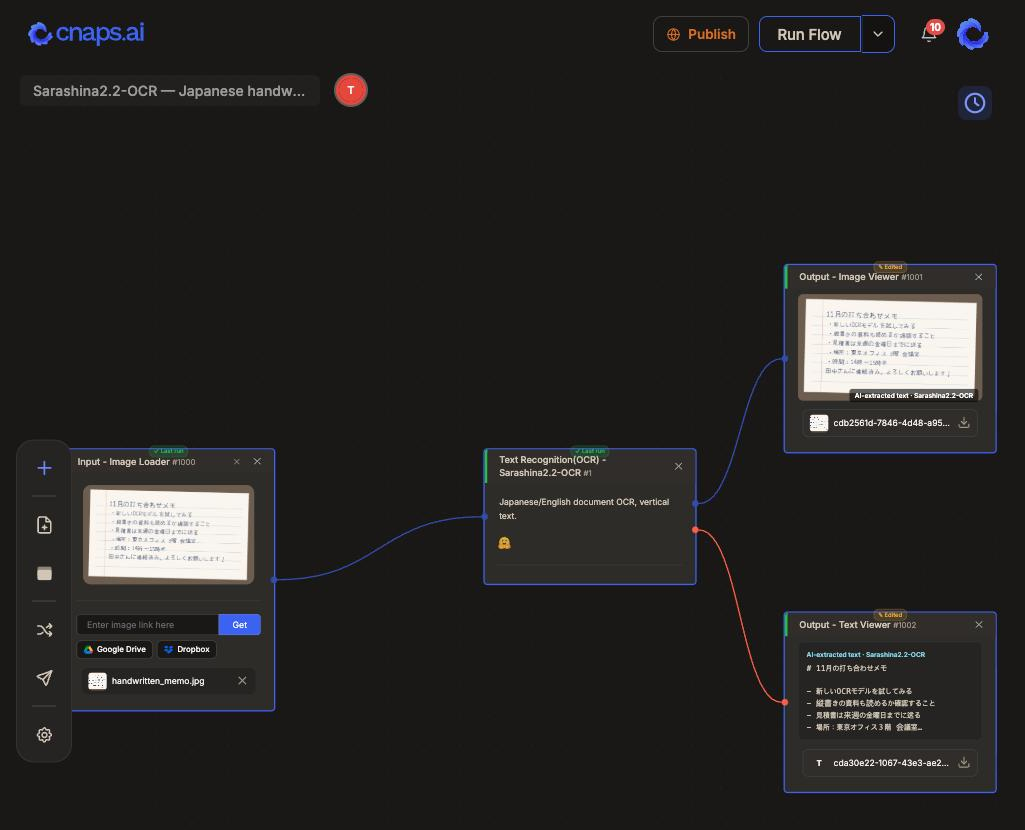
The flow in CNAPS Studio: Image Loader → Sarashina2.2-OCR → Image Viewer + Text Viewer.
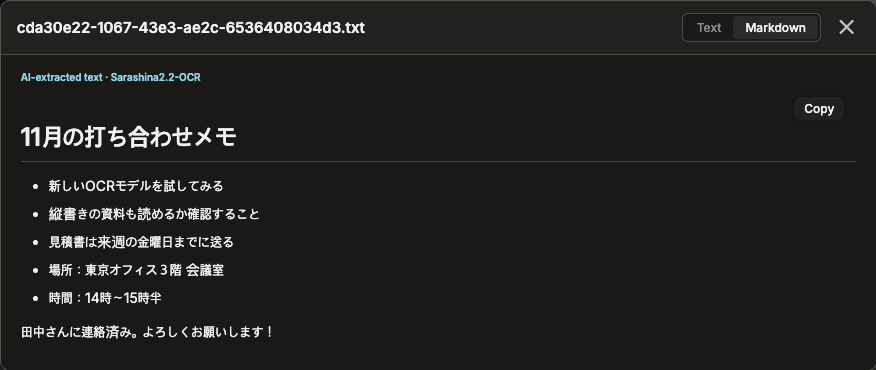
Text Viewer output, shown in Markdown mode. Use Copy to paste it straight into a doc, or connect it to a translation or LLM node in the same flow.
Choosing an OCR model
Your input | Use |
Japanese documents — vertical text, tables, formulas | Sarashina2.2-OCR |
Korean, Chinese or English printed text, high volume | PaddleOCR |
Full-page layout understanding, general multi-language documents | GLM-OCR |
Messy or cursive handwriting | DeepSeek OCR |
Performance
- Latency: 7–20 seconds per page, depending on how dense the page is
- Strongest on: printed Japanese documents with real structure — tables, columns, vertical text, formulas
- Weaker on: headers and footers, and math on old scanned pages — these are the model's two lowest olmOCR-bench categories. If your pages are aged scans with formulas, check a sample before running a batch
- Not for: Korean or Chinese (use PaddleOCR or GLM-OCR), messy or cursive handwriting (use DeepSeek OCR; neat handwritten notes worked well in our test, see the example above), or photos of casual text like signs and menus, where PaddleOCR is faster and sufficient
Technical Details
Architecture | 4B vision-language model (3B language component + vision encoder) |
Developer | SB Intuitions |
Languages | Japanese, English |
Structure recovery | Markdown text · tables as HTML · formulas as LaTeX · vertical text · figure boxes on a normalized 0–1000 range |
Runtime | GPU, cloud — no local setup |
Compliance & Provenance
Provider | SB Intuitions |
Provider type | Specialized |
License | MIT |
EU AI Act risk class | Minimal Risk |
Art. 50 transparency | OCR output is labeled "AI-extracted", not "AI-generated" |
Region availability | Available globally |
Training data summary | Pending — provider has not yet published per Art. 53(d) |
For more on how we classify models and mark outputs, see our AI Policy.
Model Source
- Model card

- License: MIT
How Sarashina2.2-OCR compares
CNAPS Studio has five OCR models. They differ mainly in language focus and in how much document structure they keep.
Model | Best for | Notes |
DeepSeekOCR | Multilingual documents; markdown output with text grounding | Vision-language model |
GLM-OCR | Tables, formulas, and structured extraction | 0.9B; OmniDocBench v1.5 94.62 |
PaddleOCR | Printed text in photos — menus, signs, IDs, screenshots | One language per node: KO / JA / ZH / EN |
Sarashina2.2-OCR | Japanese documents, including vertical text | Tables as HTML, formulas as LaTeX; 7–20 s per page |
TeleOCR | Skewed, curved, or camera-captured pages | OmniDocBench v1.6 96.87 (developer-reported) |
Rough guidance: PaddleOCR for short printed text in photos, GLM-OCR or TeleOCR for full documents with tables and formulas, Sarashina2.2-OCR for Japanese, and DeepSeekOCR for mixed-language pages. Scope notes come from each node's own documentation; the models have not been benchmarked against each other inside CNAPS Studio.
All of these run inside CNAPS Studio — compare them side-by-side.