Tag Anime Illustrations Automatically — 30,877 Danbooru Tags, Characters and Styles
PixAI Tagger looks at an anime-style illustration and returns a comma-separated list of Danbooru tags — subject, character, series, clothing, pose, composition and art style — ordered by confidence. Use it to caption or organize anime art, or to recover a prompt from an existing image. Overall micro F1 0.723 on the provider's test set. Apache 2.0.
📸 See it in action
A very emotional bowl of ramen. One illustration in, ranked Danbooru tags out. Settings: max_tags 25, include_scores on, everything else default.
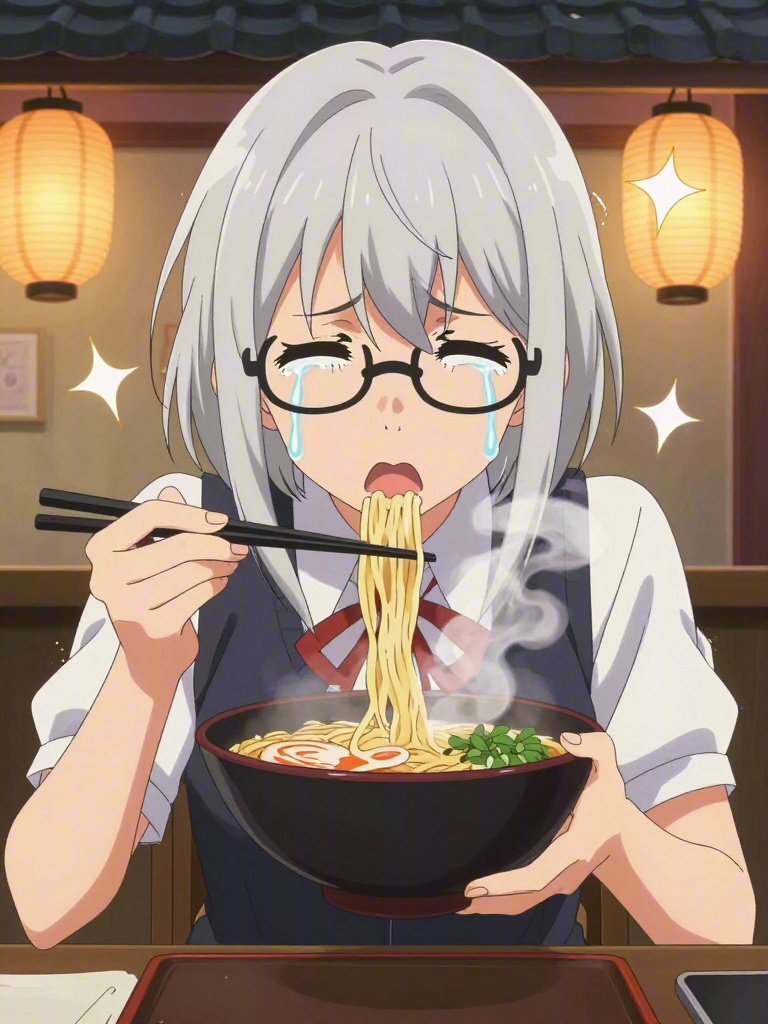
PixAI Tagger output (unedited)
noodles:0.987, chopsticks:0.953, ramen:0.947, glasses:0.939, food:0.913, 1girl:0.892, closed_eyes:0.851, eating:0.759, tears:0.717, school_uniform:0.673, holding_chopsticks:0.621, solo:0.598, bowl:0.588, short_hair:0.462, crying:0.449, holding:0.429, grey_hair:0.391, sparkle:0.363, meandros:0.314, open_mouth:0.286, anime_coloring:0.189, steam:0.172It caught the tears, the sparkles and the steam. 22 tags passed the fitted thresholds, so the 25-tag cap wasn't reached. meandros (a Greek-key border pattern) is a false positive worth filtering out. Drop include_scores when you paste the tags into an image prompt. The illustration is an original character made with Z-Image-Turbo in CNAPS Studio.
What it does
PixAI Tagger is a multi-label image tagger for anime and illustration. Give it one image and it returns tags like:
1girl, solo, long_hair, blue_eyes, school_uniform, cherry_blossoms, smile, upper_body, outdoors
The tags come from a vocabulary of 30,877 Danbooru tags in six groups: general (15,043), character (8,308), style (4,917), copyright/series (2,460), meta (145) and rating (4). Each group has its own confidence threshold, fitted by the authors.
It is not a captioner — it returns tags, never a sentence. It is not for photographs. Character and series knowledge stops at May 2026.
Problem it solves
Use case | How it helps |
Recover a prompt | Turn an existing illustration into tags you can feed to an image generator |
Organize an art library | Tag a whole collection with Batch Run for search and filtering |
Identify characters and series | Character micro F1 0.894 on the provider's test set |
Quality and rating triage | Optional meta tags (highres, scan…) and predicted content rating |
Training-data captions | Danbooru-style tags for fine-tuning anime models |
Input/Output
Input
- Image (required) — one anime-style illustration. It is resized and padded to 1008×1008, keeping the aspect ratio
Parameters
Parameter | Details |
min_threshold | 0–1, default 0. A floor under each tag's confidence. At 0, every group uses the authors' fitted threshold (general 0.17, character 0.27, copyright 0.24, style 0.15, meta 0.17, rating 0.41). A higher value raises the bar for fewer, more confident tags; a lower one changes nothing |
max_tags | 0–200, default 0 (no limit). Keeps only the top N tags. Set 20–30 when the tags go into a generation prompt, so low-confidence tags don't dilute it |
include_scores | Off by default (advanced). Writes each tag as tag:0.873. Useful for choosing a threshold; leave off for prompts |
include_meta | Off by default (advanced). Adds 145 meta tags about the file (highres, absurdres, scan, official_art…). Useful for cataloguing by quality |
include_rating | Off by default (advanced). Adds a predicted Danbooru rating — rating:g / s / q / e — with confidence. An estimate, not a moderation decision |
Output
- Text — comma-separated Danbooru tags, highest confidence first
Accuracy
Provider-reported results:
Evaluation | Score |
Overall micro F1 (full vocabulary, 80,531-image held-out split) | 0.723 |
Character micro F1 | 0.894 |
General micro F1 | 0.696 |
Common-tag benchmark, General micro F1 | 0.666 (v0.9: 0.598) |
Common-tag benchmark, Character micro F1 | 0.924 |
Where it can go wrong
- Photos and non-anime images — performance outside anime illustration is not measured
- New characters — anything after May 2026 isn't in the vocabulary
- Counts and small attributes — it can miss tags or add wrong ones; check details that matter
- Thresholds — the defaults were picked on the test set; tune them on your own images
- Not for moderation alone — don't use the rating tags as the only basis for safety, legal or age decisions. For explicit-content screening, see Adult Content Detection
Technical Details
Backbone | Fine-tuned SAM3 image encoder, 486.3M parameters |
Input resolution | 1008×1008 (resize + pad, aspect ratio kept) |
Vocabulary | 30,877 Danbooru tags in 6 groups |
Knowledge cutoff | May 2026 |
Runtime | GPU, cloud — no local setup. Fast |
Developer | PixAI Labs |
Compliance & Provenance
Provider | PixAI Labs (open weights) |
Provider type | Specialized |
License | Apache 2.0 |
EU AI Act risk class | Minimal Risk |
Art. 50 transparency | Not applicable |
Region availability | Available globally |
Training data summary | Pending — provider has not yet published per Art. 53(d) |
For more on how we classify models and mark outputs, see our AI Policy.
Model Source
- Hugging Face: https://huggingface.co/pixai-labs/pixai-tagger-v1.0
- Demo: https://huggingface.co/spaces/pixai-labs/pixai-tagger-demo
- License: Apache 2.0
How PixAI Tagger compares
Model | Best for | Notes |
PixAI Tagger | Danbooru tags for anime illustrations | 30,877 tags; characters, series, style |
Adult Content Detection | Safe vs. explicit | ViT-base; 98% on its test set |
Gender Recognition | Male vs. female for pedestrian images | BEiT; 91% on PETA |
Object Classification (ResNet) | Which of 1,000 ImageNet categories | Photos |
BLIP | A one-sentence description of any image | Captioner |
Rough guidance: PixAI Tagger for anime art; BLIP or a vision-language model such as Gemma 4 for a written description of a photo. Scope notes come from each node's own documentation; the models have not been benchmarked against each other inside CNAPS Studio.
All of these run inside CNAPS Studio — compare them side-by-side.